Real Chat Data vs Synthetic Prompts: How Wording Changes the Sources AI Assistants Cite
WaniWani Research · Real chat data and a controlled experiment, not pre-registered · October 14, 2026
We compared the prompts a US health insurance brand tracked for GEO with what its customers typed into the brand’s AI app. Real customers wrote and asked differently, and the AI engines answered them from different sources. To see how much of that comes from wording alone, we then sent six engines the same four questions in three wordings every day for 63 days, 4,305 runs in all. The wording by itself changed the sources.
TL;DR
What we did. We started from real data: the AI-generated prompts the brand tracked, compared with the openers customers typed into its AI app, both run on the same engines. Then we isolated wording. We took four intents from that app, wrote each in jargon, plain and messy form, and sent the 12 prompts every day to ChatGPT, Claude, Gemini, Perplexity, Google AI Mode and Google AI Overview.
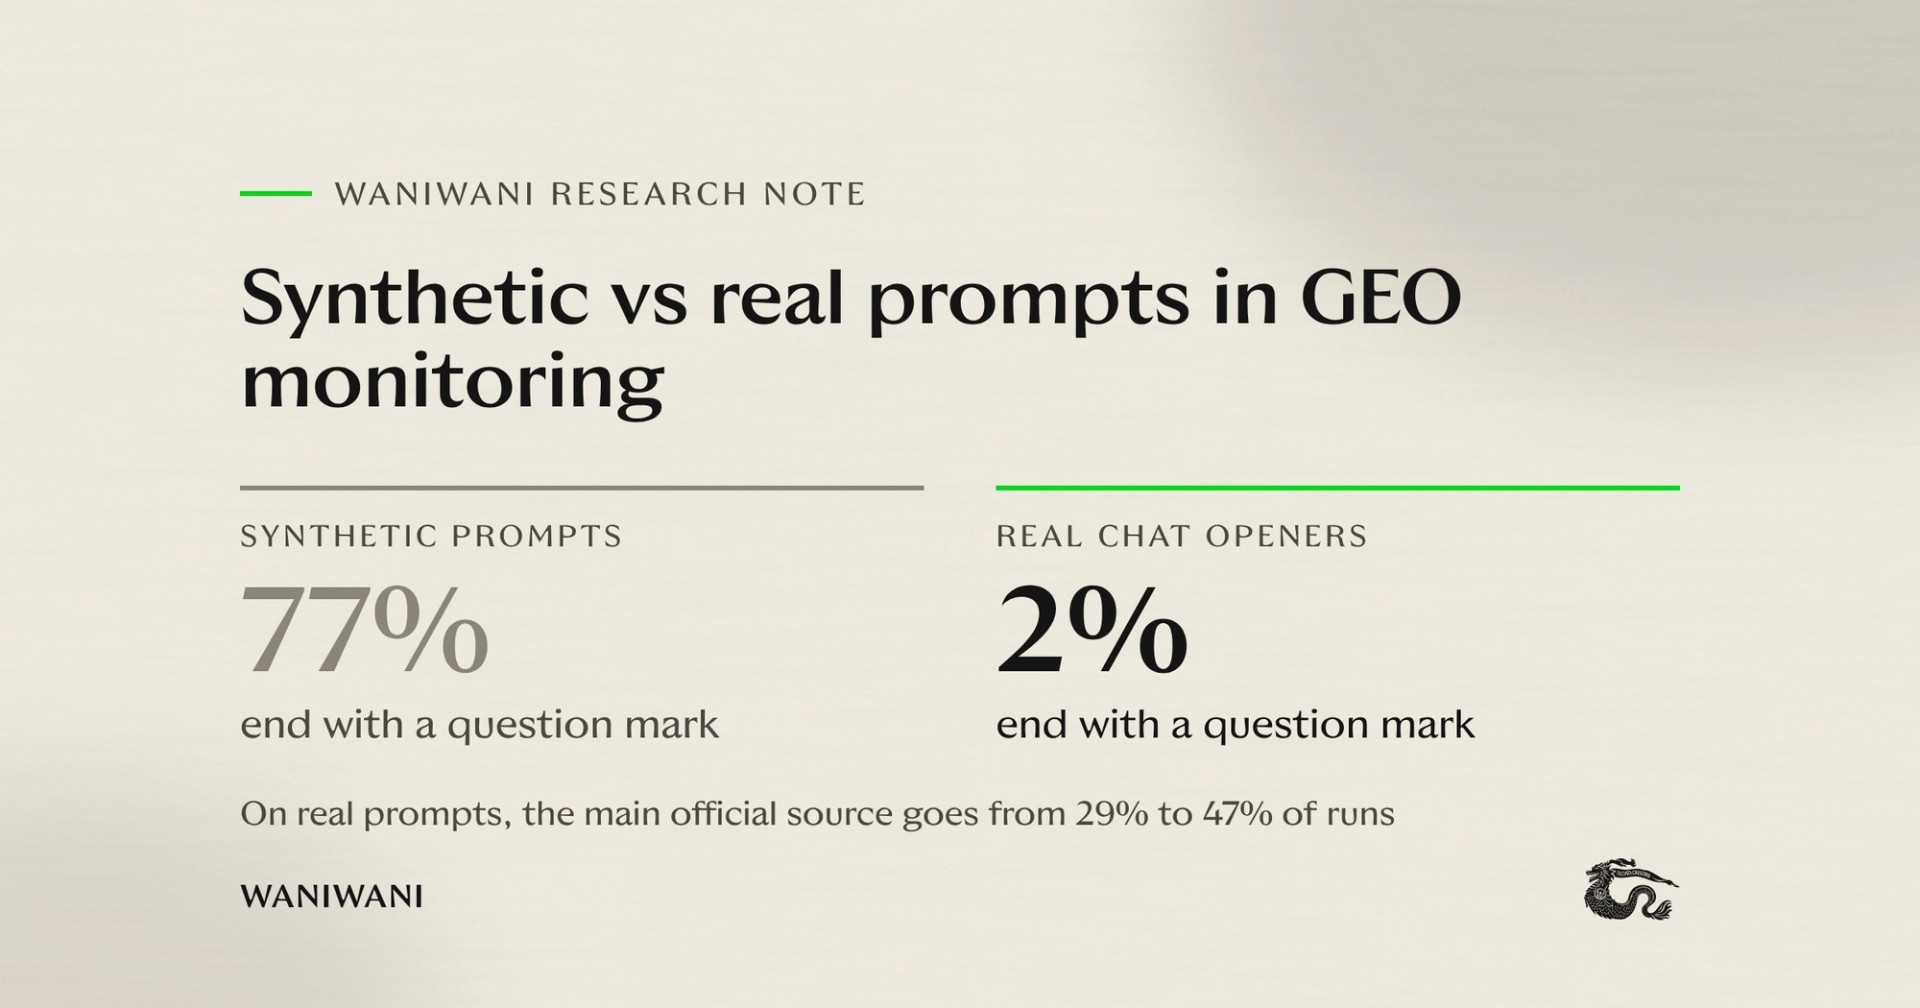
Real data. 2% of real openers end in a question mark, against 77% of generated prompts, and two life events start 65% of conversations. On real prompts the main official source rose from 29% to 47% of runs, and policy research fell from 17% to 8%.
Wording alone. With the intent held constant, jargon prompts cited government sources in 80% of runs against 61% for messy prompts (p < 10⁻²²). Reddit rose from under 1% to 10%, and the brand’s own content site fell from 11.5% to 4.4%. Only 25 to 48% of the 20 most cited domains were shared between the jargon and messy wording of the same intent.
What this means. The prompts you track decide what your GEO report shows. Prompts a model generates measure different sources from the ones real customers see. Your own conversation data gives you the words customers use and how often each need comes up, so build the tracked set from it and read the results per engine, because the engines react differently to the same wording change.
Abstract
GEO monitoring usually tracks prompts that a model generates from keywords. We first compared those prompts with real chat openers from a US health insurance AI app and ran both sets on the same engines. To test whether wording alone explains the difference, we then wrote four of the app’s intents in three registers (jargon, plain, messy) and sent the 12 prompts daily to six engines for 63 days: 4,305 completed runs, 3,549 of them from the five engines that return sources.
Real data. Real openers were rarely clean questions (2% against 77% of generated prompts), concentrated on two life events (65% of conversations) and triggered a different source mix: the main official source rose from 29% to 47% of runs and policy research fell from 17% to 8%.
Wording experiment. Wording alone moved the source mix. Jargon prompts cited government domains in 79.8% of runs (95% CI 77.4 to 82.0%) against 61.2% (58.4 to 64.0%) for messy prompts. Messy prompts cited Reddit in 10.0% of runs (8.4 to 11.9%) against 0.6% (0.3 to 1.2%). The direction held in all four intents.
Mechanism. Answer engines turn the user’s message into search queries and condition the answer on what those queries retrieve. Technical wording retrieves documents written in technical language, which are mostly official and regulatory. Situation language retrieves documents written by people in the same situation.
Contribution. Evidence from production conversations that generated prompts misstate both what customers ask and which sources answer them, plus a controlled test on six engines showing that wording alone moves the source mix. Earlier work compared survey-written prompts on one consumer query.
Motivation
Most GEO platforms generate their tracked prompts. A model reads keywords, a website or forum threads and writes “questions a customer might ask”. The output is clean: a full sentence, the industry’s vocabulary, a question mark. Brands then decide what content to write from the citation reports those prompts produce.
When the AI app of a US health insurance brand had enough live sessions, we could compare the generated prompts with what customers typed. The two looked nothing alike, and the engines cited different sources for each. That raised two questions: how far off a report built on generated prompts is, and how much of the gap comes from wording alone. Part 1 answers the first with the app’s real data. Part 2 answers the second with a controlled experiment. Health insurance was the test case, and both questions apply to any product people research in a conversation.
Part 1: What real customer data shows
The data comes from the brand’s AI app. We grouped the first message of each conversation by the situation behind it and cross-checked each group against the situation the app’s agent captured during the session. We then compared these openers with the AI-generated prompt set the brand tracked at the time. The figures in Part 1 come from that earlier analysis and were not recomputed for this note.
How do real customers phrase their questions?
Almost the opposite way to generated prompts. Only 2% of real openers are a clean question ending in “?”, and real users rarely use the industry’s own terms (5% against 32%).
| Writing style | AI-generated prompts | Real chat openers |
|---|---|---|
| Uses industry jargon | 32% | 5% |
| Clean question ending in "?" | 77% | 2% |
| All lowercase, typos, run-ons | 0% | 19% |
| Names a specific provider or product | 2% | 8% |
Real users describe what happened to them and leave the question to the assistant. Their messages also carry details that generated sets leave out, such as exact ages, the price they pay today or a hard deadline.
What do customers ask about?
A few situations. Two life events started 65% of conversations (43% and 22%), and no other situation passed 8%. The generated set gave every topic similar weight, so it under-tracked the most common event and over-tracked the second.
Which sources do real prompts trigger?
Different ones. On the same engines, real openers raised the main official source from 29% to 47% of runs. Sources that help someone in the middle of a problem gained too, such as the government body for that situation and advocacy groups. Policy research fell from 17% to 8%, and a personal finance publisher cited in 9% of generated runs never appeared on real prompts. A content plan built from the generated report would have chased that publisher and the policy research sites, which real customers barely reach.
What changes when the tracked set is rebuilt from real data?
The words and the weights. Rebuilt from the app’s openers, the tracked set came to 94 prompts, 82 of them in real chat language, and the biggest life event took 43% of them, its share of real conversations. A small branded set stayed frozen as a control.
Part 2: How wording alone changes the sources
Part 1 can’t separate wording from topic, because real openers and generated prompts differ in both. To isolate wording, we kept four of the app’s intents fixed and changed only how each question was written, then tracked the 12 prompts on six engines for 63 days.
How answer engines choose sources
Answer engines with web access do not answer from memory alone. They rewrite the user’s message into one or more search queries, retrieve documents, and generate an answer conditioned on what came back. The wording of the message shapes those queries.
That gives a testable prediction. A message written in an industry’s vocabulary should retrieve documents written in that vocabulary, such as official guidance and regulation. A message written as a personal situation should retrieve documents written as personal situations, such as forum threads and advocacy guides. If the prediction holds, the same intent asked in different words will be answered from different sources.
Research questions
The study was not pre-registered. We state the questions as exploratory and report a verdict for each.
- RQ1 (official sources). Do jargon prompts cite government and regulatory sources more often than messy prompts with the same intent?
- RQ2 (community sources). Do messy prompts cite community sources, such as Reddit, more often?
- RQ3 (brand content). Does the brand’s own content site get cited at the same rate across wordings?
- RQ4 (engine variation). Is the wording effect the same across engines?
Experiment method
Subject and intents
The prompts come from the AI app of a US health insurance brand, anonymized here. We picked four intents that real users raise often and wrote each in three registers:
| Intent | Jargon | Plain | Messy |
|---|---|---|---|
| Lost job | "What health coverage options are available after job loss and loss of employer-sponsored insurance?" | "I lost my job, how do I get health insurance for my family?" | "just got laid off with a wife and 3 kids and no insurance now, need something asap" |
| Aging off a parent's plan | "What are the enrollment options when a dependent ages off a parent's health plan at 26?" | "I'm turning 26 and losing my parents' insurance, what do I do?" | "turning 26 next month and getting kicked off my moms insurance idk where to even start" |
| Early retirement | "What health insurance options exist for early retirees before Medicare eligibility at 65?" | "I'm retiring at 62, how do I get health insurance until Medicare?" | "retiring soon at 62 and my work insurance stops before i can get medicare, not sure what to do for the gap" |
| Can't afford coverage | "What are the most affordable ACA marketplace health insurance plans available this year?" | "What's the cheapest health insurance I can get?" | "i'm broke and need health insurance but everything is so expensive, what can i even do" |
The messy versions follow the patterns in the app’s real chat openers: lowercase, no question mark, the situation first.
Instrumentation
| Parameter | Value |
|---|---|
| Window | August 12 to October 13, 2026 (63 days) |
| Prompts | 12 (4 intents × 3 wordings) |
| Engines | ChatGPT, Claude, Gemini, Perplexity, Google AI Mode, Google AI Overview |
| Country | US |
| Completed runs | 4,305 |
| Runs used for source analysis | 3,549 (Google AI Overview returned no source lists and is excluded) |
| Runs per wording, source analysis | 1,182 jargon, 1,180 plain, 1,187 messy |
Tracking ran on the WaniWani platform. Each prompt fired once a day on each engine as a fresh conversation.
Source classification
Part 2 sorts every cited domain with fixed rules, so anyone can rerun the analysis in another industry. Some categories sit inside others. The federal exchange and the regulator both have .gov domains, so their citations also count under Government.
| Category | Rule | What it captures |
|---|---|---|
| Government | Domain ends in .gov | Federal and state agencies, including the next two rows |
| Federal exchange | The federal marketplace's domain (part of Government) | Where people compare and buy plans |
| Regulator's rulebook | The federal regulator's domain (part of Government) | Rules and official guidance on coverage |
| .org site | Domain ends in .org | Mostly advocacy groups and charities, but also trade groups and some publishers |
| Community | Reddit, YouTube, Facebook, Quora and other user-generated platforms | Posts and videos by other people in the same situation |
| Brand's own content | The brand's content domain | The brand's articles and guides |
Part 1 used a different grouping. It sorted sources by the role each site plays for the reader (the main official source, policy research, personal finance publishers, advocacy groups), so its figures can’t be compared one to one with the categories here.
Each figure is the share of runs that cited at least one domain in the category. One run can count in several categories. Intervals are 95% Wilson intervals. Comparisons between jargon and messy use a two-proportion z-test.
Experiment results
Wording moves the source mix (RQ1, RQ2, RQ3)
| Source cited | Jargon | Plain | Messy | Jargon vs messy |
|---|---|---|---|---|
| Any government source | 79.8% (77.4 to 82.0) | 60.8% (58.0 to 63.6) | 61.2% (58.4 to 64.0) | p < 10⁻²² |
| Federal exchange | 71.7% (69.1 to 74.2) | 54.7% (51.8 to 57.5) | 51.6% (48.7 to 54.4) | p < 10⁻²³ |
| Regulator's rulebook | 21.4% (19.2 to 23.8) | 10.9% (9.3 to 12.8) | 6.9% (5.6 to 8.5) | p < 10⁻²³ |
| Any .org site | 57.2% (54.4 to 60.0) | 37.0% (34.3 to 39.8) | 44.7% (41.9 to 47.6) | p < 10⁻⁸ |
| Any community source | 6.8% (5.5 to 8.3) | 10.0% (8.4 to 11.8) | 14.0% (12.1 to 16.1) | p < 10⁻⁸ |
| 0.6% (0.3 to 1.2) | 4.4% (3.4 to 5.7) | 10.0% (8.4 to 11.9) | p < 10⁻²³ | |
| Brand's own content site | 11.5% (9.8 to 13.5) | 2.5% (1.8 to 3.6) | 4.4% (3.4 to 5.7) | p < 10⁻⁹ |
RQ1 supported. Government citations fall from 80% to 61% when the wording turns messy, and the regulator’s rulebook from 21% to 7%.
RQ2 supported. Reddit goes from 7 runs out of 1,182 to 119 out of 1,187. Community sources overall double.
RQ3 not supported. The brand’s content site is cited 2.6 times more often on jargon prompts than on messy ones. Its pages answer the tidy version of the question.
Jargon prompts also return more sources. 92.5% of jargon runs cited at least one source, against 76.0% of messy runs, and they cited 5.5 distinct domains on average against 4.4.
The direction holds in every intent
| Intent | Government, jargon → messy | Reddit, jargon → messy | Brand's content, jargon → messy |
|---|---|---|---|
| Lost job | 79% → 62% | 0% → 16% | 18% → 7% |
| Aging off a parent's plan | 86% → 52% | 0% → 6% | 5% → 10% |
| Early retirement | 78% → 69% | 1% → 3% | 3% → 0% |
| Can't afford coverage | 75% → 62% | 1% → 16% | 20% → 0% |
Government citations fall and Reddit citations rise in all four intents. The brand’s content falls in three of the four.
Same question, a different shortlist
For each intent we compared the 20 domains cited most often under the jargon wording with the 20 cited most often under the messy wording. The overlap (Jaccard index) ranged from 0.25 to 0.48. Half to three quarters of the top sources an engine relies on change when the same need is described in different words.
Engines react differently (RQ4)
| Engine | Government, jargon → messy | Community, jargon → messy | Brand's content, jargon → messy |
|---|---|---|---|
| ChatGPT | 95% → 90% | 2% → 2% | 0% → 0% |
| Claude | 73% → 24% | 0% → 2% | 11% → 8% |
| Gemini | 67% → 31% | 2% → 8% | 24% → 1% |
| Google AI Mode | 88% → 83% | 27% → 21% | 10% → 3% |
| Perplexity | 73% → 86% | 1% → 48% | 14% → 13% |
RQ4: the effect depends on the engine. ChatGPT barely moves. Claude and Gemini cut government citations by more than half on messy wording. Perplexity keeps citing official sources but adds community sources in almost half of messy runs. Gemini is where the brand’s content loses most: 24% of jargon runs, 1% of messy runs.
Discussion
Our view. GEO monitoring should start from first-party conversations. Part 1 shows that generated prompts misstate both what customers ask and which sources answer them. Part 2 shows why: wording alone changes half to three quarters of the top sources an engine cites. Openers from an AI app, a site chat or support logs give you the real wording and how often each situation comes up, so a GEO report is only as good as the conversations it starts from.
What we showed
- Real customer openers differ from generated prompts in wording and in topic, and they trigger a different source mix.
- In the experiment, with intent held constant, wording alone changes the sources answer engines cite, with large effects on about 1,180 runs per wording.
- Jargon wording favors official and regulatory sources. Messy wording favors community sources, Reddit above all.
- The brand’s own content performs best on the tidy wording that customers rarely use.
- The size of the effect depends on the engine.
What we did not show
- Effects on brand mentions. The brand was named in fewer than 0.3% of runs in every wording, too few to compare.
- Generalization beyond one brand. The intents come from one health insurance app.
- Conversion. We measured citations, not visits or sales.
- Why each engine differs. We observe the differences but do not test their causes.
Proposed mechanism
- The engine rewrites the user’s message into search queries.
- Jargon carries into those queries, and so does situation language.
- Retrieval matches documents written in the same register: guidance and regulation for jargon, forum threads and advocacy guides for personal situations.
- The answer is conditioned on what was retrieved, so the cited sources follow the wording.
- Engines that already lean on a few official sources (ChatGPT, Google AI Mode) move least. Engines with a wider retrieval set move most.
Limitations
- One subject, one vertical. Four intents from one US health insurance app. The direction should be tested in other categories before anyone relies on the exact numbers.
- Not pre-registered. The research questions are exploratory, and Part 1 is observational.
- One messy wording per intent. The messy prompts follow real chat patterns, but variation inside the messy register is not measured here.
- Coarse domain rules. A .org can be a trade group or a charity. The rules trade precision for portability.
- Repeated daily runs. Runs of the same prompt on the same engine are not fully independent, so the p-values overstate precision. We trust the direction because it holds in every intent and the effects are large.
- One engine without sources. Google AI Overview returned no source lists and is excluded from the source analysis.
Implications
- Track prompts in your customers’ words. Take openers from your AI app, site chat or support logs and keep the original wording, typos included.
- Weight prompts by demand. Most conversations start from a few situations. Give those situations most of the tracked prompts.
- Keep a jargon variant as a control. Tracking the same intent in jargon and messy wording shows how much of your visibility depends on a register customers rarely use.
- Write for situations as well as categories. Pages that answer “I just lost my job and need coverage for my kids” compete for the messy queries where brand content currently fades.
- Read results per engine. A wording change that does nothing on ChatGPT can halve official citations on Claude or Gemini.
- Plan for community sources. On messy wording, Reddit and other forums enter the answer on some engines in almost half of runs.
Future work
- Replicate on a second brand in a different category.
- Track several messy wordings per intent to measure variation inside the real register.
- Publish situation-language pages and measure whether the brand’s citation rate on messy prompts rises.
Frequently asked questions
What is a synthetic prompt in GEO monitoring?
A synthetic prompt is a question an LLM or a GEO platform generates to stand in for a customer query, usually from keywords, a website or forum threads. Teams track how often their brand appears in the answers. In the app we studied, 77% of generated prompts ended in a question mark, against 2% of real chat openers.
Why should GEO monitoring use real customer data?
Real conversations show the words customers use and how often each need comes up, and both change the result. In the app we studied, real chat openers raised the main official source from 29% to 47% of runs compared with generated prompts. Two life events started 65% of conversations, while the generated set weighted them like any other topic. Your AI app, site chat or support logs already hold this data.
Does the wording of a prompt change which sources an AI assistant cites?
Yes. With the intent held constant, jargon prompts cited government sources in 80% of runs and messy prompts in 61%. Reddit went from under 1% to 10%. Only 25 to 48% of the 20 most cited domains were shared between the two wordings of the same intent.
Are synthetic prompts accurate for measuring AI visibility?
Not on their own. Synthetic prompts use tidy, technical wording, which is where engines cite the most official sources and where brand content scores best. Real customers rarely write that way, so a report built only on synthetic prompts can overstate brand visibility and point content work at the wrong sources.
Why do messy prompts get more Reddit citations?
Engines turn the message into search queries before they retrieve sources. A message written as a personal situation produces queries that match other personal situations, and forum threads are full of those. In our runs, Reddit appeared in 10% of messy runs and in 0.6% of jargon runs.
Which AI engines are most sensitive to wording?
In this study, Claude and Gemini cut government citations by more than half when the wording turned messy, and Perplexity added community sources in 48% of messy runs. ChatGPT changed least: government sources stayed at 90% or more in both wordings.
Do these findings apply outside health insurance?
The intents come from a health insurance app, so the exact percentages are specific to it. The mechanism is not: engines retrieve sources that match the register of the question. Any product that people research by describing their situation should expect the same direction. Measure it on your own conversations.
Data and references
Aggregated data (citation counts per wording, intent and engine for all 4,305 runs) is available on request at research@waniwani.ai. The Princeton GEO study (Aggarwal et al., KDD 2024) measured how changes to content move citations. Spyglasses compared generated prompts with survey-written ones on a single query. For how published content moves ChatGPT’s recommendations, see WaniWani Research Vol. 1.